Korvion Korvion

How to Choose a Cloud AI Server Manufacturer?

Time:2026-10-01 Author:Mason
0%

Choosing the right cloud ai server manufacturer requires more than comparing GPU prices. It requires evidence, operational experience, and a clear understanding of your workload. A reliable provider should explain GPU models, memory capacity, networking speed, storage options, and expected performance without hiding behind vague specifications. Ask for benchmark results using workloads similar to yours, such as model training, inference, or computer vision.

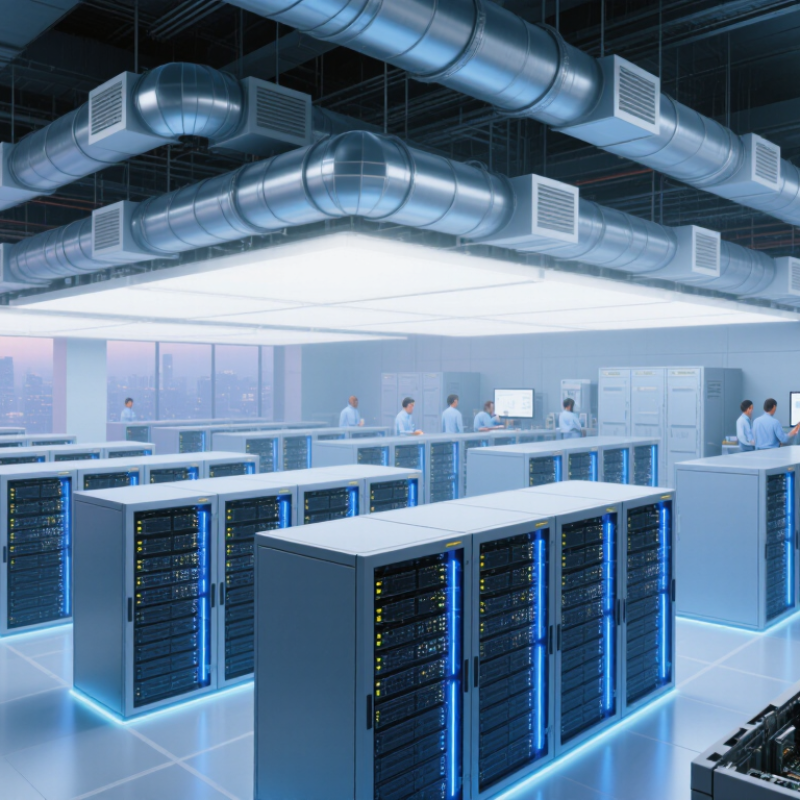
Look closely at the physical and service details. Efficient cooling matters when servers run continuously at high utilization. Power limits can affect real-world performance. Support response times matter during a failed deployment. Request information about warranties, spare parts, firmware updates, data protection, and service-level commitments. A reputable cloud ai server manufacturer should provide transparent documentation and realistic delivery schedules. Independent certifications and customer references can strengthen its credibility.

Do not choose based on brand reputation alone. Speak with technical staff. Ask how they handle GPU shortages, hardware failures, and capacity expansion. Their answers often reveal more than a polished brochure. Cost estimates should include electricity, software licenses, maintenance, data transfer, and migration work. Some manufacturers appear affordable but create expensive operational constraints later.

No supplier is perfect. That includes established manufacturers. Your evaluation should record risks, unanswered questions, and assumptions. A small pilot can expose thermal problems, unstable drivers, or weak support before a large purchase. The best decision balances performance, reliability, security, scalability, and long-term service—not simply the lowest initial quote.
How to Choose a Cloud AI Server Manufacturer?

Define Your Cloud AI Server Requirements

How to Choose a Cloud AI Server Manufacturer?

Define Your Cloud AI Server Requirements

Start with the workload, not the server catalog. Identify model size, training frequency, inference volume, latency targets, and concurrent users. A vision model serving 500 requests per second needs different hardware from a weekly language-model experiment. Record memory capacity, accelerator quantity, network speed, storage performance, and failure tolerance. Small omissions become expensive later.

The Stanford AI Index 2025 reports that training compute for notable AI models has doubled about every five months. Your manufacturer should therefore support modular upgrades, fast interconnects, and practical expansion paths. Power also deserves early attention. The International Energy Agency estimates that data centers used about 415 TWh of electricity in 2024, with demand potentially reaching 945 TWh by 2030. Ask for measured performance per watt, cooling requirements, rack density, and sustained—not peak—throughput. A perfect specification rarely exists. My first draft is often wrong.

Tips: Build a three-year demand model. Include model growth, electricity costs, maintenance, software support, and replacement delays. Request benchmark results using your own model and batch size. Check how the manufacturer handles firmware updates, spare parts, remote diagnostics, and service-level commitments. Security controls, data location, audit records, and recovery procedures should match your operational and legal requirements. The cheapest server can become costly when idle capacity, thermal limits, or support gaps appear.

Compare Manufacturer Expertise and Hardware Capabilities

Choosing a cloud AI server manufacturer requires more than comparing processor counts. Manufacturer expertise affects reliability, deployment speed, and long-term operating costs. Ask how many AI clusters the engineering team has delivered, not just how long the company has existed. Request documented test results, maintenance procedures, and customer references from similar workloads. Practical experience matters when a training job fails at 2 a.m.

Hardware capability should match your model, data, and facility. Examine accelerator performance, memory capacity, high-speed interconnects, and storage throughput. A server may advertise impressive peak performance, yet deliver less under sustained workloads. Ask for benchmark conditions and power measurements. Cooling design deserves close attention. Dense racks can create hot spots, loud fans, and unexpected energy bills. Liquid cooling may improve density, but it also requires trained technicians and careful leak monitoring.

Firmware control is another useful comparison point. Strong manufacturers provide secure update processes, compatibility testing, and clear recovery instructions. Their technical teams should explain how they diagnose failed components remotely. Support response times must be written into the service agreement. Vague promises are not enough. I once overvalued raw accelerator speed and underestimated network congestion. That mistake made an expensive cluster feel slow. No checklist is perfect. Leave room for pilot testing, because real workloads often expose weaknesses that specifications hide. A small acceptance test can reveal scheduling delays, unstable drivers, or poor thermal behavior before a full purchase.

Evaluate Performance, Scalability, and Infrastructure Compatibility

How to Choose a Cloud AI Server Manufacturer?

Evaluate Performance, Scalability, and Infrastructure Compatibility

Choosing a cloud AI server manufacturer requires more than comparing processor names. Measure real workloads instead. Test model training, inference latency, data loading, and recovery speed. A short benchmark can reveal thermal throttling or network delays.

Look closely at accelerator performance under sustained use. Ask for results using your preferred model sizes and batch settings. Memory capacity matters when datasets grow. Fast storage also reduces idle time during repeated training cycles. In practice, stable performance is often more valuable than peak specifications.

Scalability should match your operating plan. Confirm whether additional servers can join without major architecture changes. Check scheduling tools, cluster networking, cooling capacity, and power availability. Compatibility matters too. The infrastructure should support your operating system, container platform, storage protocols, monitoring tools, and security controls.

Start small.

A pilot deployment exposes practical problems early. I once assumed a larger cluster would improve every workload. It did not. Poor data placement created bottlenecks, and utilization fell below expectations. That experience changed how I evaluate suppliers. I now request failure-recovery tests, maintenance procedures, service-level details, and upgrade timelines. Manufacturer expertise should be visible in documentation and technical support, not only in sales presentations. Independent performance evidence is useful, but local testing remains essential. Infrastructure decisions are rarely perfect. Regular review keeps them honest.

How to Choose a Cloud AI Server Manufacturer?

Reference evaluation priorities for performance, scalability, and infrastructure compatibility.

The weighting reflects common AI infrastructure procurement priorities: performance focuses on accelerator capability and interconnect speed, scalability covers multi-node expansion and orchestration, while compatibility measures support for standard APIs, virtualization, storage, and networking interfaces.

Review Security Standards, Support Services, and Reliability

How to Choose a Cloud AI Server Manufacturer?

Security begins with evidence, not impressive wording. Ask for current ISO 27001 or SOC 2 reports, audit dates, and clear responsibility boundaries. Check encryption during transfer and storage. Confirm whether access uses multi-factor authentication, role-based permissions, and detailed audit logs. Data residency also matters when projects involve regulated information. Request the incident response plan before an incident happens. A certificate helps, but it is not proof of perfect daily practice.

Support quality becomes visible during a failed training run. Look for a published service-level agreement, defined response times, and an escalation path to technical engineers. Twenty-four-hour support sounds useful, but vague promises are weak. Ask whether support teams understand distributed training, driver conflicts, storage delays, and failed GPU nodes. Test the ticket system with a technical question. The answer may reveal more than a sales presentation.

Reliability needs measurable detail. Review historical uptime, maintenance notices, backup power, network redundancy, and spare hardware procedures. Ask how quickly a damaged accelerator can be replaced. Request customer references with workloads similar to yours. I once trusted an uptime percentage without checking scheduled maintenance windows. That was careless. Independent monitoring and recent performance records provide stronger evidence. Small warning signs matter. A provider that cannot explain a short outage may struggle with a larger one.

Assess Total Costs, Customization Options, and Long-Term Value

How to Choose a Cloud AI Server Manufacturer?

Choosing an AI server manufacturer starts with total cost, not the quoted chassis price. Include GPUs, CPUs, memory, networking, rack space, power, cooling, support, firmware updates, and replacement parts. Uptime Institute reported that 60% of data-center outages in its 2022 survey cost at least $100,000. A cheaper server can become expensive after one avoidable failure. Request a five-year cost model with workload utilization, energy rates, warranty terms, and technician response times. The spreadsheet will not be perfect. Test its assumptions against a pilot rack.

Customization should serve measurable workloads. Ask whether the supplier can tune GPU topology, memory capacity, storage tiers, airflow, and remote management. Confirm compatibility with your orchestration software and existing monitoring. Standard designs may deploy faster, while tailored systems can reduce idle capacity. Neither option wins automatically. Stanford’s AI Index 2024 reported that GPT-3.5-level inference costs fell more than 280-fold between November 2022 and October 2023. That change exposes a risk: hardware chosen for one model may age quickly. Favor modular nodes, replaceable accelerators, open interfaces, and clear upgrade paths. Long-term value also includes resale, repairability, training documentation, and secure data erasure.

Tips: Compare three manufacturers using the same workload test. Measure tokens per second, performance per watt, noise, and failure recovery. Ask for service-level evidence, not marketing claims. Calculate costs at 50%, 70%, and 90% utilization. Small gaps compound. Keep one assumption deliberately conservative; real operations are messier than lab results.

FAQS

How should I define my cloud AI server requirements?

Start with workload details, not a server catalog. Record model size, training frequency, inference volume, latency targets, and concurrent users. A vision system handling 500 requests per second needs different hardware. Include memory, accelerators, network speed, storage performance, and failure tolerance. Small omissions become expensive later.

Why should I plan for future expansion?

AI workloads are growing quickly. Choose modular servers, fast interconnects, and practical upgrade paths. Build a three-year demand model. Include model growth, electricity, maintenance, software support, and replacement delays. My first estimate is often wrong. Leave room for uncertainty.

How can I compare manufacturer expertise?

Ask how many similar AI clusters the engineering team has delivered. Request test results, maintenance procedures, and customer references. Experience matters when training fails overnight. A long company history proves little by itself. Practical evidence matters more.

Which hardware specifications deserve close attention?

Examine accelerator performance, memory capacity, interconnect speed, and storage throughput. Request benchmarks using your model and batch size. Ask for sustained performance, not peak figures. Check power measurements too. Numbers can look impressive.

What cooling issues should I investigate?

Ask about rack density, cooling capacity, hot spots, fan noise, and sustained thermal performance. Liquid cooling can support higher density. It also needs trained technicians and leak monitoring. Review measured performance per watt. Thermal limits may appear only after hours of use.

How should security controls be evaluated?

Request current security audit reports and recent audit dates. Check encryption during transfer and storage. Confirm multi-factor authentication, role-based access, and detailed logs. Review data location and incident response procedures. A certificate helps, but it does not prove perfect daily practice.

What support and service terms should be included?

Require written response times, escalation procedures, and replacement commitments. Ask whether engineers understand distributed training, driver conflicts, storage delays, and failed accelerator nodes. Test the ticket system with a technical question. The reply may reveal more than a presentation. Vague support is risky.

How can I test reliability before purchase?

Run a small acceptance test before ordering a full cluster. Measure scheduling delays, driver stability, network congestion, and thermal behavior. Review uptime records, maintenance windows, backup power, and network redundancy. Ask how quickly damaged hardware is replaced. Test it first.

Should I trust advertised peak performance?

Not always. Peak results may hide congestion, cooling limits, or inefficient software. Request benchmark conditions, batch size, power use, and sustained throughput. Compare results with your own workload. I once valued accelerator speed too highly and missed network congestion. That mistake was costly.

Conclusion

Choosing the right cloud ai server manufacturer begins with clearly defining your project requirements, including workload types, AI model size, processing power, memory, storage, networking, and expected user demand. Once these needs are established, compare each manufacturer’s technical expertise, hardware quality, GPU and accelerator options, and experience supporting similar applications. It is also important to evaluate performance, scalability, cooling design, power efficiency, and compatibility with your existing cloud, data center, and software infrastructure.

A reliable decision should also consider security certifications, data protection practices, technical support, warranty coverage, maintenance response times, and overall system reliability. Finally, assess the total cost of ownership rather than focusing only on the initial purchase price. Review customization possibilities, upgrade paths, energy consumption, deployment expenses, and long-term operational value. The best manufacturer should provide a balanced combination of performance, flexibility, security, dependable service, and sustainable costs, helping your organization scale AI capabilities efficiently while reducing future technology and infrastructure risks.
Mason

Mason

Mason is a seasoned marketing professional with a deep expertise in the company's offerings and a passion for driving brand awareness. With a strong background in digital marketing strategies, he has an innate ability to connect with diverse audiences and effectively communicate product benefits.......