Korvion
Choosing the right custom gpu server builder is a business decision, not merely a hardware purchase. A suitable partner must understand GPU computing, thermal design, networking, storage, and long-term maintenance. The best choice depends on actual workloads, including AI training, inference, scientific simulation, or professional rendering.
Start with the server’s intended environment. A four-GPU system may look powerful, yet limited airflow can reduce performance during sustained workloads. Check GPU compatibility, PCIe lane allocation, power delivery, memory capacity, and cooling design. Ask whether the builder validates systems under realistic loads, rather than relying only on short benchmark results. Details matter. A noisy rack can disrupt a small office. Poor cable routing can complicate routine maintenance.
Experience also reveals practical weaknesses. Reliable builders provide clear component documentation, firmware support, burn-in testing, and responsive warranty service. Their engineers should explain performance limits without hiding behind technical language. Independent certifications, customer references, and transparent replacement policies strengthen credibility. However, no supplier is perfect. A highly specialized configuration may increase delivery time or make future upgrades more difficult. That trade-off deserves honest discussion.
Compare several proposals using the same workload requirements. Request power estimates, temperature data, expansion limits, and support terms in writing. Consider the total cost of ownership, including electricity, rack space, maintenance, and downtime. The right custom gpu server builder should offer a balanced system, not the longest specification sheet. Careful questions now can prevent expensive surprises later. Mistakes still happen. The goal is controlled risk, measurable performance, and dependable support.
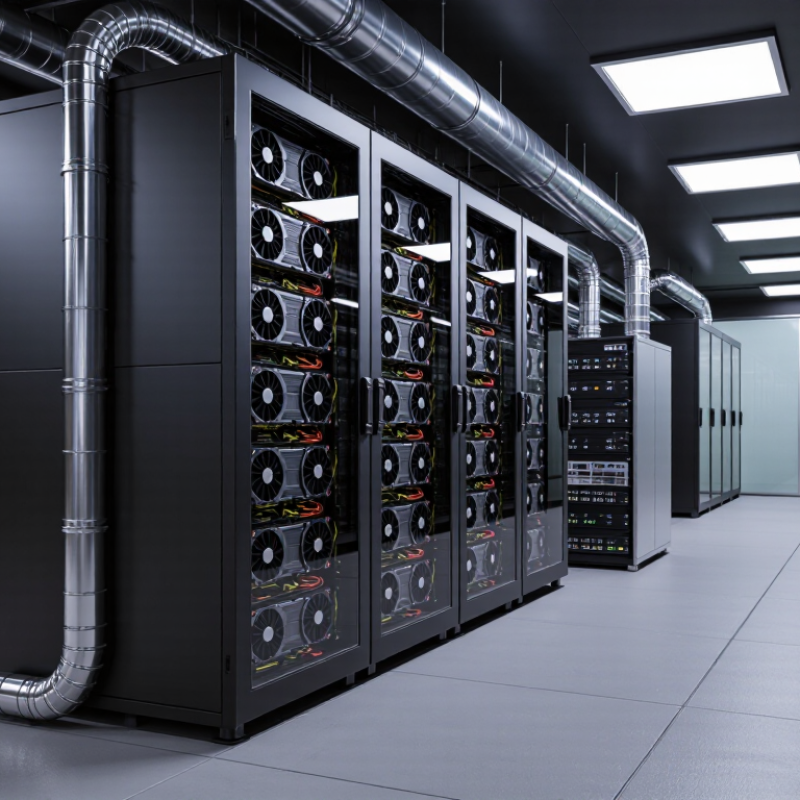
A reliable builder should begin with your workload, not a preferred hardware list. Define whether you need model training, inference, or both. MLPerf Training measures how quickly a system reaches a target quality level. MLPerf Inference examines response speed under defined accuracy and latency requirements. These results answer different questions. Do not treat them as interchangeable.
Describe your real workload with concrete details. Include model size, dataset volume, batch size, sequence length, and daily request rates. For inference, record average and worst-case latency. For training, measure time per experiment and communication overhead between GPUs. A capable builder should reproduce relevant benchmark results using stated software versions, power limits, and cooling conditions. Ask for test logs. Ask for failure rates, too. Small details matter.
Benchmarks are useful, but they are not the whole story. A server can perform well in MLPerf and struggle with your uneven data pipeline. Our first capacity estimate once looked sufficient, yet storage delays reduced utilization noticeably. That mistake changed our process. We now request a pilot using representative data before approving a larger system. Check maintenance access, firmware control, expansion options, and energy use. A custom builder earns trust by explaining trade-offs clearly, including limits they cannot remove. Fancy specifications mean little when your engineers wait beside an idle machine.
Choosing a custom GPU server begins with model requirements, not a product list. GPU memory determines whether a model runs smoothly or constantly moves data through slower system memory. A 700W-class GPU also demands careful planning. Its power draw affects the server’s power supply, cooling system, cabling, and rack capacity.
Thermal design deserves equal attention. Request airflow diagrams, sustained-load test results, and noise measurements from a comparable configuration. Short benchmark runs can hide throttling after several hours. I once underestimated the impact of room temperature on sustained workloads. That was a useful mistake. A reliable builder should explain power limits, firmware controls, warranty coverage, and replacement procedures clearly. Ask for a written parts list and an acceptance test using your real model workload. Small details matter. A capable custom server should provide stable performance, measurable headroom, and a realistic upgrade path.
How to Choose a Custom GPU Server Builder?
When selecting a custom GPU server builder, examine bandwidth as carefully as GPU compute. PCIe Gen5 x16 provides roughly 64 GB/s in each direction under ideal conditions. Real throughput falls with switch contention, firmware settings, and storage traffic. Ask the builder for measured results, not only specification sheets. A practical test should move large tensors between GPUs, memory, and high-speed storage. Check lane allocation, too. Eight GPUs may not receive full x16 connectivity simultaneously.
NVLink can create faster GPU-to-GPU paths than PCIe, but topology matters more than headline bandwidth. Request a diagram showing which GPUs communicate directly and which connections cross switches. Small topology errors can slow distributed training dramatically. InfiniBand bandwidth must also match the workload and node count. Confirm port speed, adapter placement, adaptive routing, and fabric oversubscription. A single underpowered uplink can limit an expensive cluster. Test collective operations with realistic batch sizes.
Measure before scaling.
In practice, builders sometimes quote theoretical bandwidth while omitting protocol overhead. That is a warning sign. I would request node-level and eight-node benchmarks, including latency under congestion. Cooling and power delivery deserve equal scrutiny because throttling changes every result. I have seen a balanced configuration outperform a larger system with poor lane placement. The “best” design is not always the fastest on paper.
Assess PCIe Gen5, NVLink, and InfiniBand bandwidth for scalable GPU infrastructure
The chart compares theoretical aggregate bidirectional bandwidth. PCIe Gen5 x16 provides approximately 128 GB/s, a high-speed GPU-to-GPU fabric based on fourth-generation NVLink technology can reach about 900 GB/s, and a 400 Gb/s InfiniBand connection provides approximately 100 GB/s aggregate bandwidth. Actual performance depends on topology, protocol overhead, workload, and the server builder’s implementation.
A capable builder should compare total cost of ownership, not only the server invoice. Calculate hardware, maintenance, electricity, cooling, rack space, and replacement parts over five years. Ask for measured power at idle, typical load, and maximum GPU utilization. Peak figures matter.
A 12-kilowatt rack can exceed a facility’s circuit limit during startup or workload changes. I once underestimated those short spikes. That mistake required slower deployment and extra electrical review.
PUE adds the facility’s overhead to the computing cost. A server using 100 kilowatts in a site with a 1.3 PUE effectively requires 130 kilowatts. Request the site’s current PUE, cooling method, and seasonal performance. Do not rely on a generic estimate. Local temperature and airflow can change the result. A reliable builder should model these conditions using your workload profile, not a laboratory benchmark alone.
Power density deserves equal attention. Confirm rack limits, cabinet cooling capacity, breaker ratings, UPS headroom, and floor loading. Then compare the proposed GPU layout with those limits. Rear-door cooling or liquid cooling may solve heat problems, but they add installation complexity and service requirements.
Check who owns that work. The best proposal includes test records, thermal readings, noise levels, delivery assumptions, and a clear warranty. Some estimates will still be imperfect. Leave practical headroom, because real workloads rarely remain perfectly stable.
How to Choose a Custom GPU Server Builder?
ISO 27001 should be verified, not merely displayed on a website. Ask for the certificate number, scope, issuing body, and expiration date. The scope matters. It should cover design, assembly, support, and data handling. A certificate alone cannot prove careful GPU integration. Request recent audit findings, if disclosure is permitted. This feels intrusive, but it reveals operational maturity.
Warranty terms need practical detail. Check coverage for GPUs, power supplies, memory, fans, and replacement labor. Confirm whether failures require shipping the full server. Ask about advance replacement and spare-part locations. The Uptime Institute’s 2024 outage analysis reported that 54% of serious outages created costs above $100,000. Delayed hardware repair can become an expensive scheduling problem. Test the promises. Ask for a sample RMA timeline.
Service-level agreements should define response, restoration, and escalation times. “24/7 support” means little without staffing numbers. Ask how many engineers cover your region and how GPU incidents are prioritized. Request monthly SLA reports, maintenance notices, and named escalation contacts. The 2024 Cost of a Data Breach Report placed the global average breach cost at $4.88 million, reinforcing the need for disciplined access controls and incident procedures. Yet support capacity is often difficult to verify. A video call with the operations team may expose gaps faster than polished documents. Expect imperfections, and document them before signing.
| Evaluation Dimension | What to Verify | Evidence or Contract Requirement | Recommended Benchmark | Risk Level | Weight |
|---|---|---|---|---|---|
| ISO 27001 certification | Confirm that the information security management system is certified and relevant to the services being purchased. | Current certificate, certification body, certificate number, issue date, expiry date, and defined scope. | Certificate valid on the proposal date; scope covers manufacturing, support, and customer data handling. | High | 15% |
| Certification scope and exclusions | Check whether the certificate excludes the facility, service team, cloud platform, or logistics process used for the order. | Statement of Applicability or scope statement, plus written clarification for excluded activities. | No material security activity is excluded without a documented compensating control. | High | 8% |
| Security audit transparency | Evaluate how security findings, corrective actions, and certification renewals are managed. | Recent audit summary, corrective-action process, incident-notification procedure, and annual review commitment. | Written notification of material security incidents within the agreed contractual period. | Medium | 5% |
| Warranty duration | Confirm coverage period for the complete server, GPU modules, storage, memory, power supplies, and cooling components. | Formal warranty document stating start date, covered parts, labor coverage, and exclusions. | At least 3 years for mission-critical deployments, with optional extension available. | Medium | 10% |
| Warranty response and repair | Review the process for diagnostics, replacement parts, return shipping, and on-site repair. | RMA procedure, escalation path, spare-parts policy, and maximum repair or replacement time. | Remote diagnosis within 4 business hours; replacement or repair plan within 1 business day. | High | 10% |
| Service-level agreement | Ensure service commitments are measurable and apply to hardware failures, support requests, and replacement logistics. | Signed SLA defining severity levels, response targets, restoration targets, service credits, and exclusions. | 24/7 coverage for critical incidents with a response target of 1 hour or less. | High | 15% |
| Parts availability | Assess access to compatible GPUs, power supplies, fans, memory, storage, and system boards throughout the support period. | Stocking policy, component lifecycle plan, approved-equivalent list, and end-of-life notification process. | Critical replacement parts stocked regionally or available through a documented expedited channel. | Medium | 8% |
| Technical support capacity | Verify whether the support team can handle GPU drivers, firmware, thermals, PCIe topology, power delivery, and operating-system issues. | Named escalation contacts, support organization chart, engineer qualifications, and coverage calendar. | At least two qualified escalation engineers for each supported time zone or a documented 24/7 handoff model. | High | 12% |
| Deployment and acceptance testing | Confirm that the builder validates performance, thermal behavior, firmware compatibility, and sustained GPU workloads before shipment. | Factory test report covering burn-in duration, GPU detection, memory testing, storage health, temperatures, and power draw. | Documented burn-in and acceptance checklist supplied with every configured system. | Medium | 7% |
| Configuration and change control | Evaluate how custom configurations, firmware changes, substitutions, and post-order modifications are approved. | Configuration baseline, change-record template, approval workflow, and notification requirement for substitutions. | No material component substitution without written customer approval. | Medium | 5% |
| Business continuity and capacity | Determine whether the builder can support production volume, component shortages, facility disruptions, and demand spikes. | Business continuity plan, manufacturing capacity range, secondary sourcing strategy, and lead-time reporting process. | Documented contingency plan with at least one qualified alternative source for critical components. | Medium | 5% |
| Total Evaluation Weight | 100% | ||||
Calculate memory for model weights, context length, batch size, and future growth. Leave practical headroom. Longer prompts can consume memory quickly.
No. Performance also depends on interconnect bandwidth, workload behavior, power limits, and cooling capacity. More memory may increase cost without improving your model.
Review power supplies, cabling, breakers, cooling, rack capacity, and UPS headroom. Confirm sustained power, not only the advertised peak.
Short benchmarks may hide throttling after several hours. Request airflow diagrams, thermal readings, and comparable long-duration test results.
Higher room temperatures reduce cooling headroom and may trigger slower operation. I once underestimated this effect. That mistake changed my deployment plan.
Ask for idle, typical-load, maximum-utilization, and startup-spike measurements. Peak figures matter. Workload changes can briefly exceed circuit limits.
Include hardware, electricity, cooling, maintenance, rack space, and replacement parts over five years. The server invoice is only one piece.
PUE adds facility overhead to computing power. For example, 100 kilowatts at 1.3 PUE requires 130 kilowatts. Check rack cooling, floor loading, and breaker limits.
Use your real model workload, not only laboratory benchmarks. Request a written parts list, performance records, warranty terms, and replacement procedures. Some estimates will remain imperfect. Plan extra capacity.
Choosing the right custom gpu server builder requires more than comparing hardware prices. Start by defining your workloads through measurable MLPerf Training and Inference benchmarks, then match GPU memory capacity and 700W-class thermal design power to the size, complexity, and performance goals of your models. A suitable configuration should also provide enough PCIe Gen5, NVLink, and InfiniBand bandwidth to support efficient multi-GPU communication and future scaling.
The evaluation should extend to the data center environment and long-term operating costs. Compare total cost of ownership, power usage effectiveness, cooling requirements, and rack-level power density with your facility’s limits. Before making a decision, verify the builder’s ISO 27001 practices, warranty coverage, service-level agreements, replacement procedures, and technical support capacity. The best partner will offer a balanced solution that delivers reliable performance, manageable energy consumption, secure operations, and responsive assistance throughout the server’s lifecycle.